Last updated: 14 october 2026. Written by Rodion Salnik, CTO and Co-founder, Brocoders.
Refactor, replatform or rebuild? Lift and shift vs refactor for a live product
Your partners say the data stopped syncing again. Every release breaks something a customer notices, and the runtime your product sits on goes out of support next year. Then someone on the leadership call asks the question this guide answers: should we refactor, replatform or rebuild?
For a product that already has paying customers, the answer comes from one place: the single constraint that blocks the next stage of the business. Pick the smallest change that removes it, decide it module by module, and protect whatever already earns money.
This guide covers live products. If your build stalled before launch, the decision works differently, and our project takeover team handles that case.
TL;DR: Rehost, replatform, refactor and rebuild fix different problems. Write down the one constraint blocking your business, start at the smallest option that removes it, and run the decision per module instead of per system. Find what already earns money first (rankings, billing, a live integration) and keep it out of the rebuild scope.
The options on the table: 7 Rs, plus rebuild
The cloud migration options are rehost, replatform, refactor, repurchase, retire, retain and relocate. Most guides still call them the 6 Rs, while AWS Prescriptive Guidance now lists 7. A live product needs one more option that the list leaves out: rebuild.
- Rehost (lift and shift). Move the app to the cloud as it is, with no code or architecture changes. It is the fastest way out of a data centre.
- Replatform (lift, tinker and shift). Move onto managed services under the same code: self-managed PostgreSQL to Amazon RDS, hand-run servers to a managed container service.
- Refactor (re-architect). Change how the code is organised while the product behaves the same for users. Re-architecting is the larger version, for example splitting a monolith into services.
- Repurchase. Replace the app with a SaaS product someone else maintains.
- Retire. Switch off what nobody uses.
- Retain. Keep a workload where it is, on purpose, with a date to revisit.
- Relocate. Move a whole environment to a cloud host without changing the apps.
- Rebuild. Write a new implementation and carry over the data and business rules your customers depend on.
If your product already runs in the cloud, rehost drops off the list and rebuild joins it. The rest of this guide compares the four options SaaS teams weigh most: rehost, replatform, refactor and rebuild.
Why teams pick the wrong one
Teams pick the wrong option when they start from the destination. They ask what the product should look like in two years before they write down what it cannot do today, and the scope grows from there.
We see the same pattern in assessments. A team starts a re-architecture to fix "scaling", and months later someone traces the slowdown to a self-managed database that a managed service would have fixed in weeks. The destination was reasonable; the entry point cost them a year.
Every adviser in this decision earns more from some answers than from others. Cloud providers earn more when you move to managed and cloud-native services. Agencies earn more from long incremental programmes or from rebuilds. We in Brocoders sell rebuilds too, so judge our advice by one test: can we name the case where we would tell you to skip the rebuild? The CondoGenie section below is that case.
Rehost vs replatform vs refactor vs rebuild
Rehost changes where the product runs, replatform changes what runs underneath it, refactor changes how the code is organised, and rebuild replaces the code itself.
| Rehost | Replatform | Refactor | Rebuild | |
|---|---|---|---|---|
| Also called | Lift and shift | Lift, tinker and shift | Re-architect (when the structure changes) | Rewrite |
| What changes | Where it runs | Managed services under the same code | Code structure, same behaviour | The implementation; data and business rules carried over |
| Fixes | Data-centre exit, hardware cost | Infrastructure overhead, ops load | A design that blocks scale or delivery | A product that cannot carry the next customer |
| Cannot fix | Anything in the code | Architecture limits | A dead runtime with no tests | A spec nobody can write down |
| Live-product risk | Low | Low to medium | Medium, scope grows | High, unless you keep what earns |
| Brocoders proof | CondoGenie | Lake, HeyPractice (split) |
A rehost gets you to the cloud fast, and then you pay cloud prices for on-premise behaviour until you move further.
Replatforming is the most underused option for live SaaS. A managed database, autoscaling and containers can remove a lot of operational load without touching the code, although they cannot move a limit that lives in the architecture.
Refactoring pays off when the design itself blocks scale or delivery and your team can still describe what the product does. Rebuilding pays off when the product cannot carry the next customer and you can write the spec down. A rebuild carries the most risk when it touches what already earns, which is why the rule below asks about that directly.
The bottleneck-first rule
Start at the smallest option that removes your constraint, and make the call module by module. Four questions get you there.
1. What specific constraint blocks the business goal? Write it in one sentence. "Property managers won't sign up because availability and pricing change every 5 minutes and our sync can't keep up" is a constraint. "The system doesn't scale well" is a feeling, and you cannot pick an option from it.
2. Can a smaller option fix it? If a managed database removes the constraint, a refactor is premature. If the constraint lives in the code, no infrastructure change will move it.
3. What scope risk can you absorb while you keep shipping? Refactors and rebuilds grow once they start. Decide how much of the roadmap you can pause, and for how long.
4. What earns money and must not move? Search rankings, billing, a live integration, a compliance state. Find it before anyone prices the work, because it shrinks the rebuild scope.
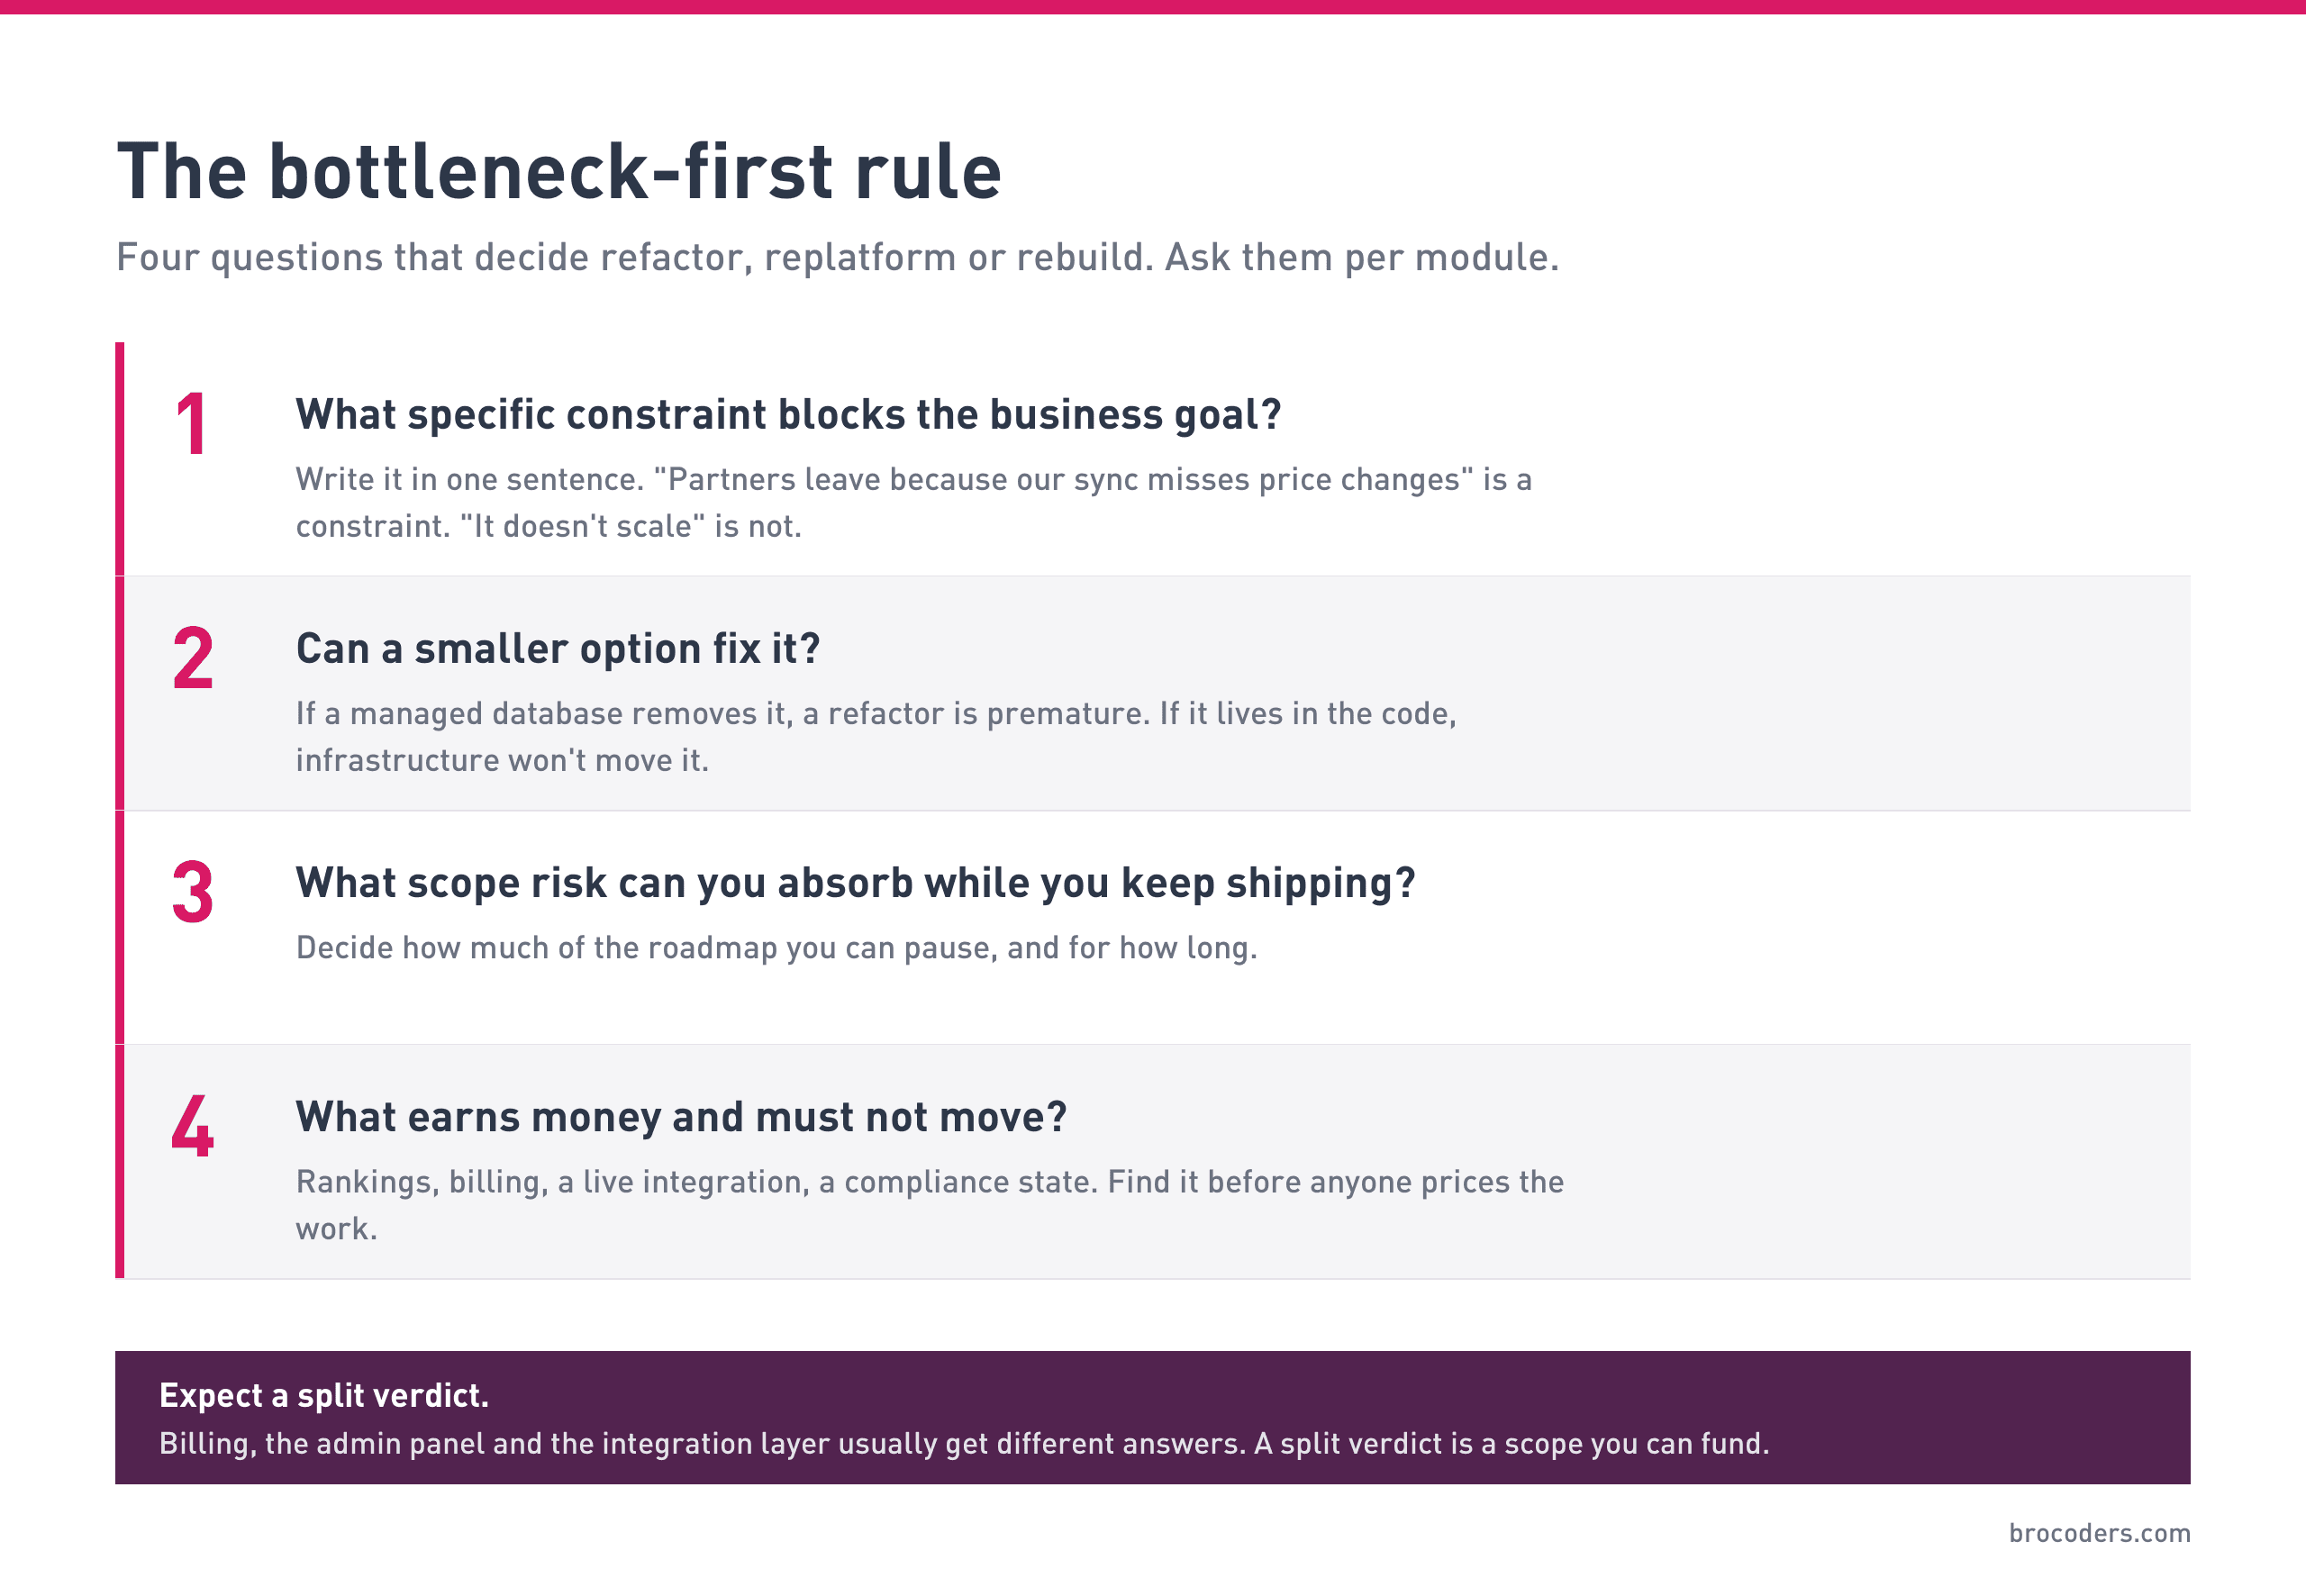
Run the four questions on each module separately. Billing, the admin panel and the integration layer usually come back with different answers, and a split verdict is a scope you can fund. For the code-level version of this test, our guide to refactor vs rewrite for legacy software scores each module on four signals.
Which signal points where
Rehost fits a data-centre exit on a fixed date, and little else for a product that already runs in the cloud.
Replatform when:
- The business logic works and the infrastructure creates the overhead
- Your team runs servers, backups and scaling by hand
- You need lower ops load this quarter without a code freeze
Refactor when:
- The design blocks scale or independent releases, and you have load tests or incident data to show it
- Your team can describe what the product does without reading the code
- The runtime is supported, or can be upgraded in place
Rebuild when:
- The product cannot carry the next customer, integration or market
- Nothing catches a broken release except a customer
- The stack is at or near end of life
- You can write down what the new version must do
Rebuild part when: one part of the system earns money in a way a new stack would not improve. That part stays, and the rebuild happens around it. For a larger architectural move, our comparison of monolith vs microservices covers the trade-offs.
Three live products, three answers
Three products with paying users brought us versions of the same question, and each got a different answer.
Lake: rebuild, but keep what earns
Lake.com, a US vacation rental marketplace, launched on a WordPress build. Property managers refused to use the platform until it synced with their property management systems (PMS), and pricing and availability change every 5 minutes. The connection worked, and the data stopped syncing after it.
Lake had no staging environment, so our first step was a staging environment and controlled deploys. Then came the split. We kept the WordPress homepage, blog and city pages, because they carried the organic rankings. We rebuilt everything else in 3 months, with a team of 5 at kickoff.
Under the ongoing partnership, connected properties grew from about 500 to 40,000, an 80x increase, across 6 PMS partnerships. The site recorded +210% tracked events and +40% visitors. David Ciccarelli, Lake's founder, explained why he picked us: "He was the only one of 150 vendors who asked to speak with the integration partner that we were working with."
Read how we rebuilt Lake's platform, or browse Lake.com and our other migration case studies.
HeyPractice: a split verdict
HeyPractice, a German AI learning platform for sales teams, had an MVP with users and a funded deadline: relaunch and improve the software within 4 to 5 months. We audited the repository and the staging environment before we quoted.
The verdict came back split. We kept the database structure, models and migrations, and replaced the rest. The data model was legible and the domain had not changed, so the rebuild scope shrank to the parts that blocked the relaunch.
CondoGenie: refactor in place, on live revenue
CondoGenie, a condominium management platform, has worked with us from 2018 to present, eight years. Its recent constraint was a runtime clock, and a rebuild would not have fixed it faster than an upgrade.
So we upgraded in place while the product kept running: a Rails upgrade released in August 2025, a Playwright test migration from June to September 2025, a Stripe API migration in February 2026, and a frontend toolchain move off unsupported Node 14 and 18 to Node 24.19.0 LTS, in progress now. Over the partnership, active users grew from 1,398 in 2019 to 19,324 in 2025. When the code is understood and the runtime is the problem, refactoring in place is the cheaper answer.
The other Rs
A full assessment covers the remaining options too.
- Repurchase. Replace the app with SaaS when a vendor covers the use case, which is common for CRM, HR and accounting tools.
- Retire. AWS suggests retiring "zombie" apps with average CPU and memory use below 5%, and reviewing "idle" apps at 5 to 20% over 90 days (AWS Prescriptive Guidance).
- Retain. Keep a workload where it is because of compliance, hardware dependencies or a planned replacement, and set a date to revisit it.
- Relocate. Move an environment to a cloud host as a block, without changing the apps inside it.
How we make the call
We sell the decision separately from the build. Our Diagnostic produces an architecture map, a dependency graph, a security and data review, a test-coverage assessment, a prioritised risk register, and a written refactor-versus-rebuild recommendation that is permitted to say do not rebuild.
Before we price anything, we ask to speak to the dependency the product lives on: the integration partner, the payment provider, the system that holds the data. At Lake, that question decided the project. If you want that verdict for your own product, our application modernization team starts there.
Where to start. Write your constraint in one sentence this week, then run the four questions on your 3 most troublesome modules. You will probably get a split verdict, and that is a scope you can plan and fund. For the wider picture, read our guide to legacy application modernization, or talk to our application modernization team about your product.
Frequently Asked Questions
Start with the one constraint that blocks your business and pick the smallest option that removes it. Replatform fixes infrastructure overhead, refactor fixes a design that blocks scale while behaviour stays the same, and rebuild fixes a product that cannot carry the next customer. Decide per module, and keep whatever already earns money out of the rebuild.
Lift and shift (rehosting) moves an app to the cloud with no changes. Replatforming moves it onto managed services, such as a managed database, while the code stays the same.
Replatforming changes what runs underneath the code. Refactoring changes the code's structure while users see the same behaviour.
Choose refactoring when the design itself blocks scale or independent releases and you can show it with load tests or incident data. If you can describe the constraint in one sentence and it lives in the code, refactor. If it lives in servers, backups or scaling, replatform first.
When the product cannot carry the next customer or integration, nothing catches a broken release, and you can write down what the new version must do.
Yes, and it is usually the right answer. HeyPractice kept its database structure, models and migrations; Lake kept the WordPress pages that carried its rankings.
The 6 Rs are rehost, replatform, refactor, repurchase, retire and retain. AWS now adds relocate, which makes 7. For a live SaaS product already in the cloud, the practical list is replatform, refactor, rebuild or rebuild part.
Scope drives the timeline more than the option does. Lake's platform rebuild took 3 months with a team of 5 at kickoff; CondoGenie's runtime upgrades shipped as separate releases across 2025 and 2026.
A half-built product has no customers to protect yet, so the decision turns on what the previous team left behind. Our project takeover team covers that situation.